Aim
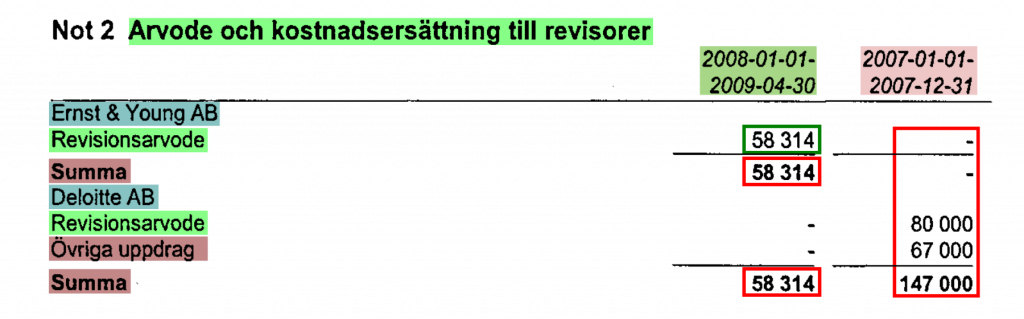
Extract auditing fees from approx. 0,8 million medium and large Swedish companies’ scanned annual reports in PDF-format.
Analysis
The documents are first analysed by sampling the dataset. Patterns and features are identified and the difficulty of the task is estimated.
Approach
An iterative approach was used for processing the data.
- Model tuning
- Parameter tuning
- Testing
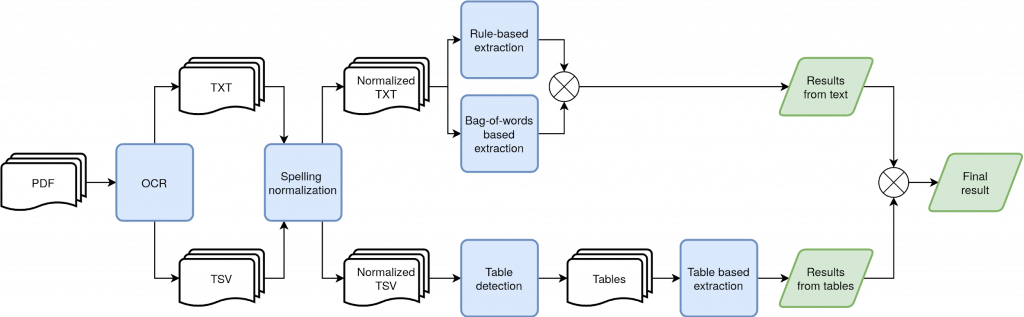
In order to produce the best final outcome, results from three different models were combined:
- Rule-based model
- Bag-of-words model
- Table-based model
Pipeline
Optical Character Recognition (OCR)
Tesseract OCR with an adjusted Swedish language model was used for OCR. Output in two different formats was produced:
- plain text files
- tab separated files with additional information (word positions, confidence level etc.)
The OCR results varied significantly depending on the scan quality and the complexity of the report layouts.
Spelling normalization
The popular spellchecking library HunSpell with a customized Swedish dictionary was used to identify and correct misspelled words. Correcting misspellings due to OCR errors significantly improves keyword matching.
Finding and extracting the audit fees
Rule-based extraction
Relevant keywords and phrases are used to find the fees. Negative keywords and phrases used to exclude the non relevant fees.
Bag-of-words-based extraction
In a bag-of-words model, text is represented as a multiset of words, counting how many times a word is used while disregarding its position.
To localize the fees, a relevance score is computed based on the number of positive and negative keywords.
Table-based extraction
Firstly, the document areas that are in table format are identified based on the layout. Columns are then identified and clustered and the processed tables for each document are exported.
After the tables have been detected, relevant keywords and phrases in the tables are located and column headings are identified. Finally, the relevant fees are located and extracted.
Normalising and combining the results
The fees are processed and normalised by removing whitespace, decimal points, adjusting the range etc. The results obtained by all three models are then combined into the final result.
Testing
The final results are tested against manually processed test data for:
- Accuracy
number of files with correct results / number of files with returned results - Extraction rate
number of documents with fee extracted / number documents containing fee